config.example.yaml
yaml · 487 bytes
# CPU smoke-test profile for the Cell2location Visium tutorial.
# The article's full run uses 73,260 reference cells and 30,000 spatial epochs.
data_dir: data
results_dir: results
seed: 0

reference:
  max_cells_per_type: 200
  max_genes: 5000
  max_epochs: 20
  batch_size: 2048
  num_samples: 50
  categorical_covariates:
    - Method

spatial:
  max_spots: 1000
  n_cells_per_location: 30
  detection_alpha: 20
  max_epochs: 50
  batch_size: null
  num_samples: 20
  top_celltypes: 8
run_smoke_test.sh
bash · 874 bytes
#!/usr/bin/env bash
set -euo pipefail

ROOT="$(cd "$(dirname "${BASH_SOURCE[0]}")" && pwd)"
PYTHON_BIN="${PYTHON_BIN:-~/miniforge3/envs/cell2location_cpu/bin/python}"
export PYTHONNOUSERSITE=1
export MPLBACKEND=Agg

cd "${ROOT}"
mkdir -p results logs

echo "== 00 download =="
bash scripts/00_download_data.sh

echo "== 01 prepare =="
"${PYTHON_BIN}" scripts/01_prepare_tutorial_data.py --config config.example.yaml

echo "== 02 reference model =="
REF_EPOCHS="${REF_EPOCHS:-20}"
"${PYTHON_BIN}" scripts/02_train_reference.py \
  --config config.example.yaml \
  --max-epochs "${REF_EPOCHS}"

echo "== 03 spatial mapping =="
SP_EPOCHS="${SP_EPOCHS:-50}"
"${PYTHON_BIN}" scripts/03_map_spatial.py \
  --config config.example.yaml \
  --max-epochs "${SP_EPOCHS}"

echo "== done =="
ls -lh results/fig_cell2location_spatial.pdf results/sp.h5ad results/reference_signatures.tsv
scripts/00_download_data.sh
bash · 1207 bytes
#!/usr/bin/env bash
set -euo pipefail

ROOT="$(cd "$(dirname "${BASH_SOURCE[0]}")/.." && pwd)"
DATA="${ROOT}/data"
mkdir -p "${DATA}"

download() {
  local url="$1"
  local target="$2"
  if [[ -s "${target}" ]]; then
    echo "exists: ${target}"
    return
  fi
  echo "download: ${url}"
  curl -L --retry 3 --continue-at - --output "${target}" "${url}"
}

download \
  "https://cf.10xgenomics.com/samples/spatial-exp/1.0.0/V1_Human_Lymph_Node/V1_Human_Lymph_Node_filtered_feature_bc_matrix.h5" \
  "${DATA}/V1_Human_Lymph_Node_filtered_feature_bc_matrix.h5"
download \
  "https://cf.10xgenomics.com/samples/spatial-exp/1.0.0/V1_Human_Lymph_Node/V1_Human_Lymph_Node_spatial.tar.gz" \
  "${DATA}/V1_Human_Lymph_Node_spatial.tar.gz"
download \
  "https://cell2location.cog.sanger.ac.uk/paper/integrated_lymphoid_organ_scrna/RegressionNBV4Torch_57covariates_73260cells_10237genes/sc.h5ad" \
  "${DATA}/sc.h5ad"

if [[ ! -f "${DATA}/spatial/tissue_positions_list.csv" ]]; then
  tar -xzf "${DATA}/V1_Human_Lymph_Node_spatial.tar.gz" -C "${DATA}"
fi

echo "data ready:"
ls -lh \
  "${DATA}/V1_Human_Lymph_Node_filtered_feature_bc_matrix.h5" \
  "${DATA}/V1_Human_Lymph_Node_spatial.tar.gz" \
  "${DATA}/sc.h5ad"
scripts/01_prepare_tutorial_data.py
python · 5630 bytes
#!/usr/bin/env python3
"""Prepare the Cell2location Visium tutorial as a small CPU smoke test."""

from __future__ import annotations

import argparse
from pathlib import Path

import anndata as ad
import numpy as np
import pandas as pd
import scanpy as sc
import yaml
from cell2location.utils.filtering import filter_genes


ROOT = Path(__file__).resolve().parents[1]


def load_config(path: Path) -> dict:
    with path.open("r", encoding="utf-8") as handle:
        return yaml.safe_load(handle)


def resolve(value: str | Path) -> Path:
    path = Path(value)
    return path if path.is_absolute() else ROOT / path


def remove_mt(adata: ad.AnnData) -> int:
    if "SYMBOL" not in adata.var:
        adata.var["SYMBOL"] = adata.var_names.astype(str)
    mt_mask = adata.var["SYMBOL"].astype(str).str.startswith(("MT-", "MT.")).to_numpy()
    if mt_mask.any():
        adata.obsm["MT"] = adata[:, mt_mask].X.toarray()
        adata = adata[:, ~mt_mask].copy()
    return int(mt_mask.sum())


def stratified_subsample(
    adata: ad.AnnData,
    label_key: str,
    max_per_label: int,
    seed: int,
) -> ad.AnnData:
    rng = np.random.default_rng(seed)
    selected: list[int] = []
    groups = adata.obs.groupby(label_key, observed=True).indices
    for indices in groups.values():
        indices = np.asarray(indices)
        n = min(max_per_label, len(indices))
        selected.extend(rng.choice(indices, size=n, replace=False).tolist())
    return adata[np.sort(np.asarray(selected))].copy()


def main() -> int:
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("--config", default=str(ROOT / "config.example.yaml"))
    parser.add_argument("--max-cells-per-type", type=int, default=None)
    parser.add_argument("--max-genes", type=int, default=None)
    parser.add_argument("--max-spots", type=int, default=None)
    args = parser.parse_args()

    cfg = load_config(Path(args.config))
    data_dir = resolve(cfg["data_dir"])
    results_dir = resolve(cfg["results_dir"])
    results_dir.mkdir(parents=True, exist_ok=True)
    ref_cfg = dict(cfg["reference"])
    spatial_cfg = dict(cfg["spatial"])
    max_cells = args.max_cells_per_type or int(ref_cfg["max_cells_per_type"])
    max_genes = args.max_genes or int(ref_cfg["max_genes"])
    max_spots = args.max_spots or int(spatial_cfg["max_spots"])

    h5 = data_dir / "V1_Human_Lymph_Node_filtered_feature_bc_matrix.h5"
    ref_path = data_dir / "sc.h5ad"
    if not h5.is_file() or not ref_path.is_file():
        raise FileNotFoundError("run scripts/00_download_data.sh first")
    if not (data_dir / "spatial" / "tissue_positions_list.csv").is_file():
        raise FileNotFoundError("spatial/ is missing; extract the 10x spatial tarball")

    print("loading Visium ...", flush=True)
    spatial = sc.read_visium(
        data_dir,
        count_file=h5.name,
        load_images=True,
    )
    spatial.var_names_make_unique()
    spatial.obs["sample"] = "V1_Human_Lymph_Node"
    spatial.var["SYMBOL"] = spatial.var_names.astype(str)
    if "gene_ids" in spatial.var:
        spatial.var.set_index("gene_ids", drop=True, inplace=True)
    mt_genes = remove_mt(spatial)

    rng = np.random.default_rng(int(cfg["seed"]))
    n_spots = min(max_spots, spatial.n_obs)
    keep_spots = np.sort(rng.choice(spatial.n_obs, size=n_spots, replace=False))
    spatial = spatial[keep_spots].copy()

    print("loading scRNA reference ...", flush=True)
    reference = ad.read_h5ad(ref_path)
    reference.var["SYMBOL"] = reference.var_names.astype(str)
    if "GeneID-2" in reference.var:
        reference.var.set_index("GeneID-2", drop=True, inplace=True)
    reference.var_names_make_unique()
    selected = filter_genes(
        reference,
        cell_count_cutoff=5,
        cell_percentage_cutoff2=0.03,
        nonz_mean_cutoff=1.12,
    )
    reference = reference[:, selected].copy()
    reference = stratified_subsample(
        reference,
        "Subset",
        max_cells,
        int(cfg["seed"]),
    )
    for key in ("Subset", "Sample", "Method"):
        if key in reference.obs:
            reference.obs[key] = reference.obs[key].astype(str).astype("category")

    shared = reference.var_names.intersection(spatial.var_names)
    if len(shared) == 0:
        raise ValueError("no shared genes between reference and spatial data")
    if len(shared) > max_genes:
        ref_shared = reference[:, shared].X
        if hasattr(ref_shared, "toarray"):
            n_cells = np.asarray((ref_shared > 0).sum(axis=0)).ravel()
        else:
            n_cells = (ref_shared > 0).sum(axis=0)
        order = np.argsort(n_cells)[::-1][:max_genes]
        shared = shared[order]
    reference = reference[:, shared].copy()
    spatial = spatial[:, shared].copy()

    reference.write_h5ad(results_dir / "prepared_reference.h5ad")
    spatial.write_h5ad(results_dir / "prepared_spatial.h5ad")

    summary = pd.DataFrame(
        [
            ("reference_cells", reference.n_obs),
            ("reference_genes", reference.n_vars),
            ("reference_celltypes", reference.obs["Subset"].nunique()),
            ("spatial_spots", spatial.n_obs),
            ("spatial_genes", spatial.n_vars),
            ("mt_genes_removed", mt_genes),
            ("max_cells_per_type", max_cells),
            ("max_genes", max_genes),
            ("max_spots", max_spots),
        ],
        columns=["metric", "value"],
    )
    summary.to_csv(results_dir / "prepare_summary.tsv", sep="\t", index=False)
    print(summary.to_string(index=False), flush=True)
    return 0


if __name__ == "__main__":
    raise SystemExit(main())
scripts/02_train_reference.py
python · 3789 bytes
#!/usr/bin/env python3
"""Train the reference Cell2location RegressionModel on a reduced reference."""

from __future__ import annotations

import argparse
import time
from pathlib import Path

import anndata as ad
import matplotlib
import matplotlib.pyplot as plt
import pandas as pd
import scvi
import yaml

matplotlib.use("Agg")

from cell2location.models import RegressionModel


ROOT = Path(__file__).resolve().parents[1]


def load_config(path: Path) -> dict:
    with path.open("r", encoding="utf-8") as handle:
        return yaml.safe_load(handle)


def resolve(value: str | Path) -> Path:
    path = Path(value)
    return path if path.is_absolute() else ROOT / path


def main() -> int:
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("--config", default=str(ROOT / "config.example.yaml"))
    parser.add_argument("--max-epochs", type=int, default=None)
    parser.add_argument("--batch-size", type=int, default=None)
    parser.add_argument("--num-samples", type=int, default=None)
    args = parser.parse_args()

    cfg = load_config(Path(args.config))
    ref_cfg = dict(cfg["reference"])
    results_dir = resolve(cfg["results_dir"])
    ref = ad.read_h5ad(results_dir / "prepared_reference.h5ad")
    epochs = args.max_epochs or int(ref_cfg["max_epochs"])
    batch_size = args.batch_size or int(ref_cfg["batch_size"])
    num_samples = args.num_samples or int(ref_cfg["num_samples"])
    scvi.settings.seed = int(cfg["seed"])
    plt.rcParams["pdf.fonttype"] = 42

    print(
        f"reference: {ref.n_obs} cells x {ref.n_vars} genes; "
        f"celltypes={ref.obs['Subset'].nunique()}; epochs={epochs}",
        flush=True,
    )
    covariates = [
        key for key in ref_cfg.get("categorical_covariates", [])
        if key in ref.obs
    ]
    RegressionModel.setup_anndata(
        adata=ref,
        batch_key="Sample",
        labels_key="Subset",
        categorical_covariate_keys=covariates or None,
    )
    mod = RegressionModel(ref)
    started = time.time()
    mod.train(
        max_epochs=epochs,
        batch_size=batch_size,
        train_size=1,
        accelerator="cpu",
        enable_progress_bar=False,
    )
    elapsed = time.time() - started

    mod.plot_history(5)
    fig = plt.gcf()
    fig.savefig(results_dir / "reference_training_history.pdf", bbox_inches="tight")
    plt.close(fig)

    ref = mod.export_posterior(
        ref,
        sample_kwargs={"num_samples": num_samples, "batch_size": batch_size},
    )
    model_dir = results_dir / "reference_model"
    mod.save(str(model_dir), overwrite=True)
    ref.write_h5ad(results_dir / "reference_exported.h5ad")

    factor_names = list(ref.uns["mod"]["factor_names"])
    if "means_per_cluster_mu_fg" in ref.varm:
        columns = [f"means_per_cluster_mu_fg_{name}" for name in factor_names]
        signatures = ref.varm["means_per_cluster_mu_fg"][columns].copy()
    else:
        columns = [f"means_per_cluster_mu_fg_{name}" for name in factor_names]
        signatures = ref.var[columns].copy()
    signatures.columns = factor_names
    signatures.index = ref.var_names
    signatures.to_csv(results_dir / "reference_signatures.tsv", sep="\t")

    pd.DataFrame(
        [
            ("reference_cells", ref.n_obs),
            ("reference_genes", ref.n_vars),
            ("celltypes", len(factor_names)),
            ("epochs", epochs),
            ("batch_size", batch_size),
            ("num_samples", num_samples),
            ("elapsed_seconds", round(elapsed, 2)),
        ],
        columns=["metric", "value"],
    ).to_csv(results_dir / "reference_summary.tsv", sep="\t", index=False)
    print(f"reference model done in {elapsed:.1f}s", flush=True)
    return 0


if __name__ == "__main__":
    raise SystemExit(main())
scripts/03_map_spatial.py
python · 5653 bytes
#!/usr/bin/env python3
"""Map reference signatures onto Visium spots and render a PDF preview."""

from __future__ import annotations

import argparse
import time
from pathlib import Path

import anndata as ad
import matplotlib
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import scvi
import yaml

matplotlib.use("Agg")

from cell2location.models import Cell2location


ROOT = Path(__file__).resolve().parents[1]


def load_config(path: Path) -> dict:
    with path.open("r", encoding="utf-8") as handle:
        return yaml.safe_load(handle)


def resolve(value: str | Path) -> Path:
    path = Path(value)
    return path if path.is_absolute() else ROOT / path


def abundance_frame(adata: ad.AnnData, key: str) -> pd.DataFrame:
    if key not in adata.obsm:
        raise KeyError(f"missing obsm[{key!r}]")
    value = adata.obsm[key]
    frame = value.copy() if isinstance(value, pd.DataFrame) else pd.DataFrame(
        value, index=adata.obs_names
    )
    prefix = key.replace("_cell_abundance_w_sf", "cell_abundance_w_sf") + "_"
    if len(frame.columns) and all(str(c).startswith(prefix) for c in frame.columns):
        frame.columns = [str(c)[len(prefix):] for c in frame.columns]
    return frame


def main() -> int:
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("--config", default=str(ROOT / "config.example.yaml"))
    parser.add_argument("--max-epochs", type=int, default=None)
    parser.add_argument("--num-samples", type=int, default=None)
    args = parser.parse_args()

    cfg = load_config(Path(args.config))
    spatial_cfg = dict(cfg["spatial"])
    results_dir = resolve(cfg["results_dir"])
    spatial = ad.read_h5ad(results_dir / "prepared_spatial.h5ad")
    signatures = pd.read_csv(results_dir / "reference_signatures.tsv", sep="\t", index_col=0)
    shared = np.intersect1d(spatial.var_names, signatures.index)
    if len(shared) == 0:
        raise ValueError("no shared genes between spatial data and signatures")
    spatial = spatial[:, shared].copy()
    signatures = signatures.loc[shared]
    epochs = args.max_epochs or int(spatial_cfg["max_epochs"])
    num_samples = args.num_samples or int(spatial_cfg["num_samples"])
    scvi.settings.seed = int(cfg["seed"])
    plt.rcParams["pdf.fonttype"] = 42

    print(
        f"spatial: {spatial.n_obs} spots x {spatial.n_vars} genes; "
        f"celltypes={signatures.shape[1]}; epochs={epochs}",
        flush=True,
    )
    Cell2location.setup_anndata(adata=spatial, batch_key="sample")
    mod = Cell2location(
        spatial,
        cell_state_df=signatures,
        N_cells_per_location=float(spatial_cfg["n_cells_per_location"]),
        detection_alpha=float(spatial_cfg["detection_alpha"]),
    )
    started = time.time()
    mod.train(
        max_epochs=epochs,
        batch_size=spatial_cfg.get("batch_size"),
        train_size=1,
        accelerator="cpu",
        enable_progress_bar=False,
    )
    elapsed = time.time() - started
    spatial = mod.export_posterior(
        spatial,
        sample_kwargs={"num_samples": num_samples, "batch_size": spatial.n_obs},
    )
    mod.save(str(results_dir / "spatial_model"), overwrite=True)
    spatial.write_h5ad(results_dir / "sp.h5ad")

    mod.plot_QC()
    fig = plt.gcf()
    fig.savefig(results_dir / "spatial_qc.pdf", bbox_inches="tight")
    plt.close(fig)

    means = abundance_frame(spatial, "means_cell_abundance_w_sf").clip(lower=0)
    q05 = abundance_frame(spatial, "q05_cell_abundance_w_sf").clip(lower=0)
    top = means.mean(axis=0).sort_values(ascending=False).head(
        int(spatial_cfg["top_celltypes"])
    ).index.tolist()
    coords = np.asarray(spatial.obsm["spatial"])
    table = pd.DataFrame(
        {
            "spot_id": spatial.obs_names.astype(str),
            "x": coords[:, 0],
            "y": coords[:, 1],
        }
    )
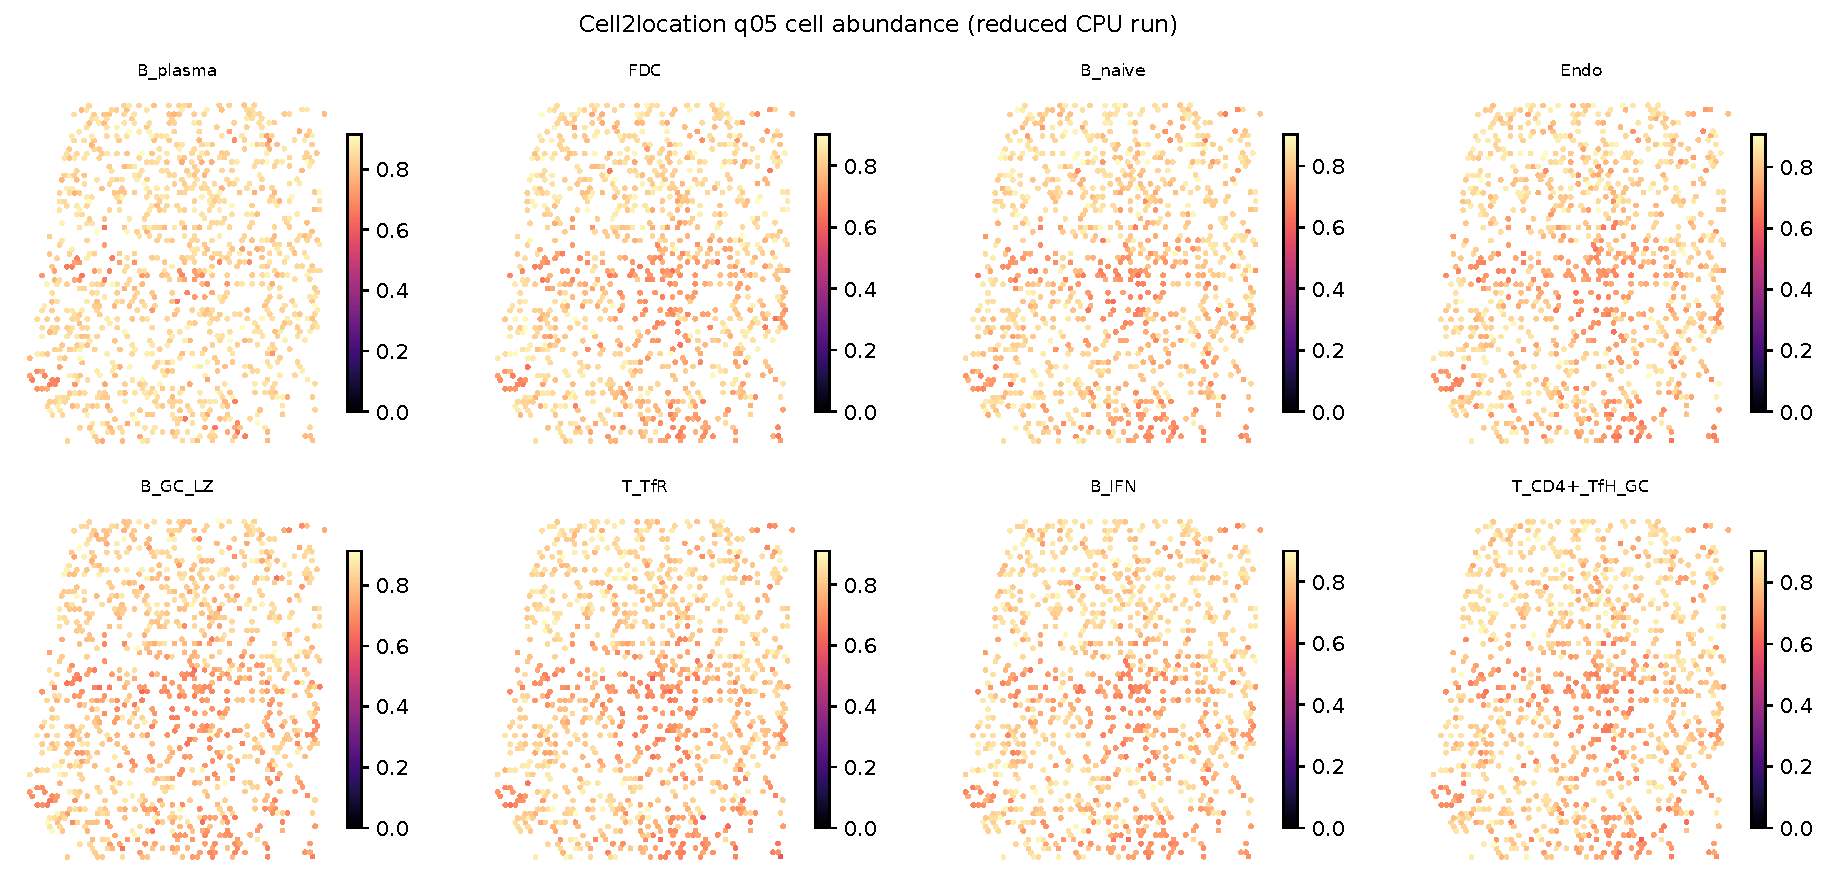
    for celltype in top:
        table[f"q05__{celltype}"] = q05[celltype].to_numpy()
    table.to_csv(results_dir / "cell2location_abundance_top.tsv", sep="\t", index=False)

    ncols = 4
    nrows = int(np.ceil(len(top) / ncols))
    fig, axes = plt.subplots(nrows, ncols, figsize=(3.2 * ncols, 3.0 * nrows))
    axes = np.atleast_1d(axes).ravel()
    for ax, celltype in zip(axes, top):
        values = q05[celltype].to_numpy(dtype=float)
        vmax = max(float(np.nanquantile(values, 0.992)), 1e-8)
        scatter = ax.scatter(
            coords[:, 0],
            -coords[:, 1],
            c=values,
            s=5,
            cmap="magma",
            vmin=0,
            vmax=vmax,
            linewidths=0,
        )
        ax.set_title(celltype, fontsize=8)
        ax.set_aspect("equal")
        ax.axis("off")
        fig.colorbar(scatter, ax=ax, fraction=0.046, pad=0.02, shrink=0.75)
    for ax in axes[len(top):]:
        ax.axis("off")
    fig.suptitle("Cell2location q05 cell abundance (reduced CPU run)", fontsize=11)
    fig.tight_layout()
    fig.savefig(results_dir / "fig_cell2location_spatial.pdf", bbox_inches="tight")
    plt.close(fig)

    pd.DataFrame(
        [
            ("spatial_spots", spatial.n_obs),
            ("spatial_genes", spatial.n_vars),
            ("celltypes", signatures.shape[1]),
            ("epochs", epochs),
            ("num_samples", num_samples),
            ("elapsed_seconds", round(elapsed, 2)),
            ("top_celltypes", ", ".join(top)),
        ],
        columns=["metric", "value"],
    ).to_csv(results_dir / "spatial_summary.tsv", sep="\t", index=False)
    print(f"spatial mapping done in {elapsed:.1f}s", flush=True)
    return 0


if __name__ == "__main__":
    raise SystemExit(main())
scripts/04_export_qc.py
python · 1242 bytes
#!/usr/bin/env python3
"""Regenerate training-history and mapping-QC PDFs from saved models."""

from __future__ import annotations

from pathlib import Path

import anndata as ad
import matplotlib
import matplotlib.pyplot as plt

matplotlib.use("Agg")

from cell2location.models import Cell2location, RegressionModel


ROOT = Path(__file__).resolve().parents[1]
RESULTS = ROOT / "results"


def main() -> int:
    plt.rcParams["pdf.fonttype"] = 42
    ref = ad.read_h5ad(RESULTS / "prepared_reference.h5ad")
    reference_model = RegressionModel.load(str(RESULTS / "reference_model"), ref)
    reference_model.plot_history(5)
    plt.gcf().savefig(
        RESULTS / "reference_training_history.pdf",
        bbox_inches="tight",
    )
    plt.close()

    spatial = ad.read_h5ad(RESULTS / "sp.h5ad")
    spatial_model = Cell2location.load(str(RESULTS / "spatial_model"), spatial)
    spatial = spatial_model.export_posterior(
        spatial,
        sample_kwargs={"num_samples": 20, "batch_size": spatial.n_obs},
    )
    spatial_model.plot_QC()
    plt.gcf().savefig(RESULTS / "spatial_qc.pdf", bbox_inches="tight")
    plt.close()
    print("QC PDFs regenerated")
    return 0


if __name__ == "__main__":
    raise SystemExit(main())